react-native-agent-bridge
Let an AI agent read and drive a React Native app through the components themselves: snapshot, query, act, allow. The UI SDK agent bridge, for native apps.
npm i react-native-agent-bridgenpx react-native-agent-bridge demoComponents in your React Native app register their own actions. An agent calls them directly, instead of reading the accessibility tree and tapping its way through the screen.
UI SDK gave web components this: snapshot() reads what is on the page, act() calls it, an allow callback gates every step. It covers React, Vue, Svelte, Solid and Web Components. It does not cover React Native. This is the same shape for native apps.
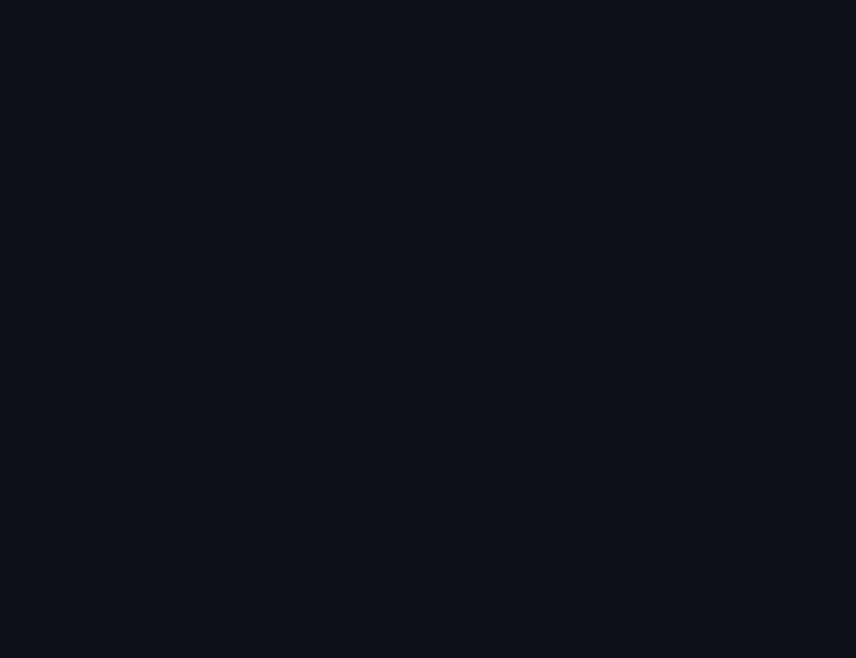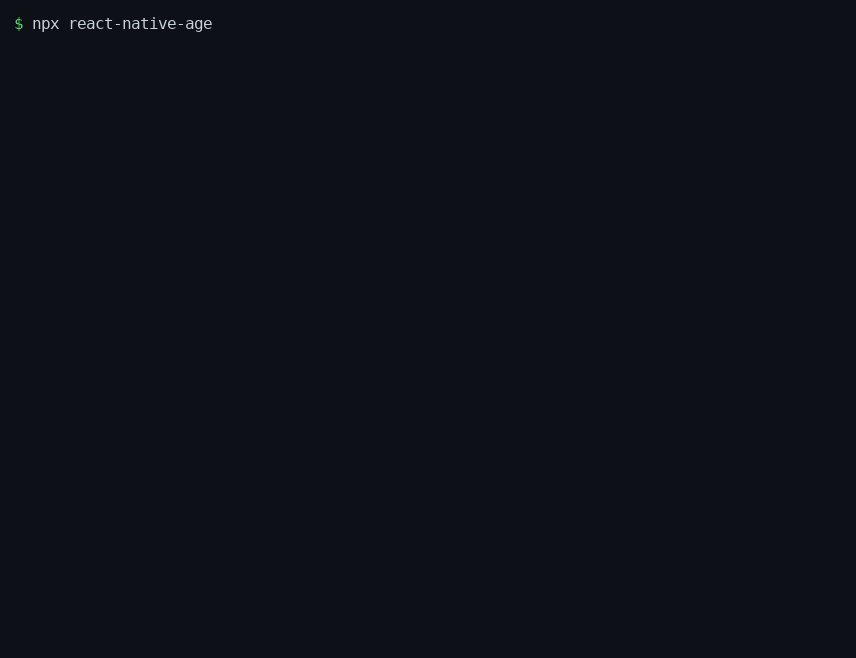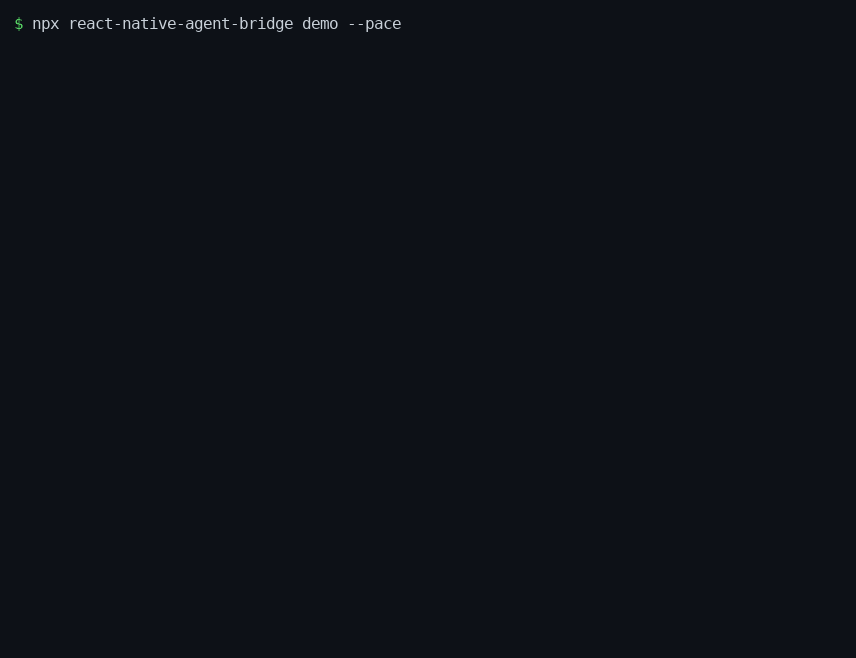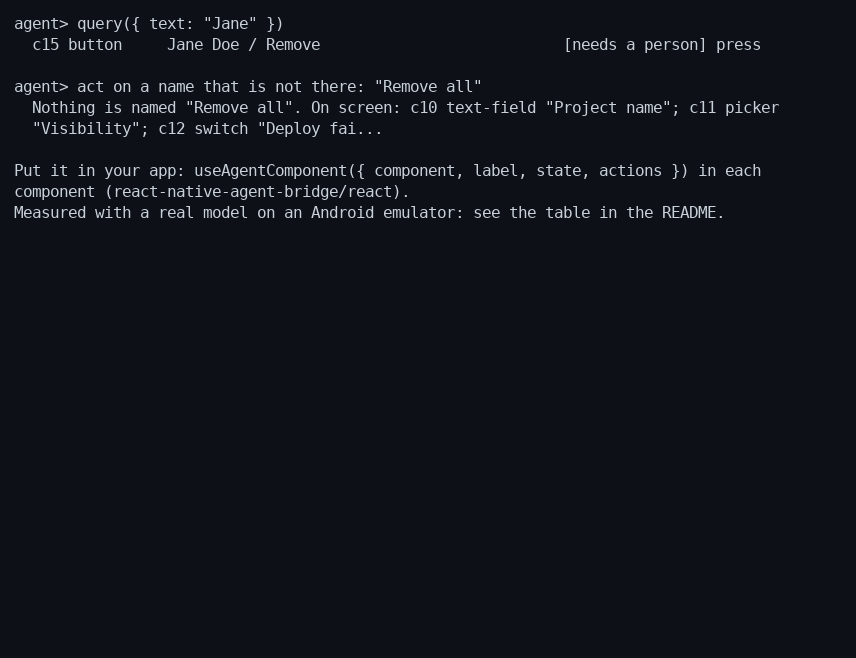
Try it with no device, no model and no key (a fixture settings screen and a script that plays the agent):
Measured on an Android emulator, same task, Claude Sonnet 5.5, 3 runs each, all correct:
| Tools | Tool calls | Input tokens | Time | Cost |
|---|---|---|---|---|
| bridge | 8 | 30,372 | 10 s | $0.066 |
| accessibility tree | 14 | 98,875 | 49 s | $0.204 |
Side-by-side capture (left: bridge, 11 s; right: accessibility tree, 48 s; real time, software-GPU emulator). One task, one model, near-identical runs: what this does and does not show. Raw runs, transcripts and the harness are in bench/model/ (in the GitHub repo, not in the npm package).
API
| Tool | Does |
|---|---|
snapshot |
Every component on screen: ref, kind, label, row text, state, items when few, the actions it takes now. Long screens end with more. |
query |
Find components by whole-word text, by kind, or list one picker's items with within. |
act |
Steps [{ ref, action, args }] in order, in one call. Names a component by ref, label, row text, or row label. Stops at the first failure and says what is on screen. Returns the state of every component it touched. |
Marks on a component, per UI SDK's data-agent-*:
confirm: "Deletes the account.": a person must do this. The step waits onallow, or fails withNeeds a personwhen there is none.hidden: true: the agent never sees it.secret: ["value"]: filled but private, reads[redacted].
allow(step, { signal }) decides every step before it runs and can be async (an alert on the device); signal aborts when the wait ends. timeout defaults to 5 minutes.
Install
npm i react-native-agent-bridge
Zero runtime dependencies. react is an optional peer, only for the hook.
The one line that changes in a component you already have is useAgentComponent({ component, label, state, actions }); the rest of the component stays as it is.
Use
import { useState } from "react";
import { Switch } from "react-native";
import { useAgentComponent } from "react-native-agent-bridge/react";

function DeployAlerts() {
  const [on, setOn] = useState(false);
  useAgentComponent({
    component: "switch",
    label: "Deploy failures",
    row: "Email",
    state: { checked: on },
    actions: { setChecked: (v: boolean) => setOn(v) },
  });
  return <Switch value={on} onValueChange={setOn} accessibilityLabel="Deploy failures" />;
}
import { createAgent, agentTools, call } from "react-native-agent-bridge";

// createAgent() reads the same global registry that useAgentComponent() writes to, so there is nothing to connect:
// every mounted component that called the hook shows up in agent.snapshot().
const agent = createAgent({ allow: (step) => (step.confirm ? askThePerson(step.confirm) : true) }); // askThePerson: your own alert, returns boolean | Promise<boolean>

agent.snapshot();
// [{ ref: "c1", component: "switch", label: "Deploy failures", row: "Email", checked: false, actions: ["setChecked"] }]
await agent.act({ steps: [{ ref: "Email Deploy failures", action: "setChecked", args: [true] }] });
// agentTools is an array of { name, description, inputSchema }: hand it to any model API as its tools.
// Route each tool call the model makes through call(), using the call's name and its arguments object as `input`:
const modelToolCall = { name: "act", input: { steps: [{ ref: "Email Deploy failures", action: "setChecked", args: [true] }] } };
await call(agent, modelToolCall); // { name: "snapshot" } and { name: "query", input: { text: "Deploy" } } work the same way
Transports
- MCP.
createMcpHandler(agent)fromreact-native-agent-bridge/mcpanswersinitialize,tools/listandtools/calland returns one JSON-RPC response per request.serveOverSocket(agent, socket)wires it to React Native'sWebSocket.actis annotated consequential; labels are annotated untrusted. - Phone agents.
react-native-agent-bridge/device-agentregistersapp_snapshot,app_act,app_queryon a react-native-device-agentToolRegistryand answers{ available: false }when the foreground app has no bridge, so the loop falls back to the accessibility tree.
Why this exists
Our night test lane drives our Expo app builds with an agent on an emulator, reading the screen and tapping. Between 2026-11-18 and 2026-11-19 that lane ran 154 times for $90.39 ($0.59 and about 18 turns a run), 4 of them cut off at the turn limit. That is a lot of money for tapping through screens, and it is the cost this is meant to cut.
To see what a bridge changes, we ran UI SDK's benchmark task on a project-settings screen (three tabs, 24 members with a menu on each row, a confirm dialog, switches grouped by channel; rename, set visibility, make one member admin, remove another and confirm, flip two switches, save) in an Expo app on an Android emulator (examples/expo-app in the repo, built with Gradle, Android 15 image, software GPU), driven by a model through each tool set. Model: Claude Sonnet 5.5 through OpenRouter. 3 runs per tool set; every run saved exactly once and the saved settings were correct.
| Tools | Correct | Tool calls | Input tokens | Output tokens | Time | Cost |
|---|---|---|---|---|---|---|
bridge (snapshot, query, act) |
3/3 | 8 | 30,372 | 524 | 10 s | $0.066 |
accessibility tree (get_screen, tap, type_text, scroll, back) |
3/3 | 14 | 98,875 | 646 | 49 s | $0.204 |
The bridge used 1.75x fewer tool calls, 69% fewer input tokens, 4.8x less time and a third of the cost. UI SDK reports about 75% fewer tokens on a browser; this is the same order on a phone. Reproduce from a clone of the repo with bench/model/run.ts (needs adb, the built app, an OPENROUTER_API_KEY); results and one transcript per tool set are in bench/model/results/.
What this does and does not show:
- One task, one screen, one model. Treat it as one data point, not a rate.
- The three runs were near-identical (same token counts to the digit; only the time differed), so "median of 3" says little about spread. We did not vary the prompt or the temperature.
- Input tokens are summed over every turn and nothing was prompt-cached, which is the accounting that favours neither side but overstates both against a cached setup. Both used the same loop, system prompt and task text.
- The tree side was not slowed by scrolling here. The two members the task touches are near the top of the list, so the tree agent never scrolled. A task that needs a row 20 deep would cost the tree more; the bridge sees all registered rows at once.
- How you name actions matters a lot. Our first version of the example gave each member row a generic
press("Remove")action. The model could not see the button names, guessed, and needed 30 tool calls and 211k input tokens ($0.45) for the same task (one run, kept as a warning). After naming the actions what they do (makeAdmin,remove,cancel) the numbers in the table came out. The bridge shows an agent the action names; make them say what they do. - Time on the emulator includes screen reads of about 1 s each on a software-GPU emulator; the bridge's read is a function call.
On a production app, one real flow
The settings screen above is a rig. We also put the hook on a few screens of one of our production Expo apps (an events app: SDK 54, React Native 0.81, new architecture), in a branch that was never released, built locally for the same emulator (no EAS, no store pipeline), against its staging backend with a test account. The flow: start signed out; sign in; open Settings from the profile screen; turn two privacy switches on and one off. The check reads the backend as that user (consent rows and the profile), not the screen. The app side is 3 text/button hooks on the sign-in screen, 1 on the sign-in prompt, 1 on the profile screen, 3 switch rows in Settings, and a 20-line connector; about 25 lines in all.
| Tools | Correct | Tool calls | Input tokens | Output tokens | Time | Cost |
|---|---|---|---|---|---|---|
| bridge | 3/3 | 8 | 19,754 | 490 | 18 s | $0.044 |
| accessibility tree | 3/3 | 10 | 38,888 | 498 | 36 s | $0.083 |
Medians of 3, Sonnet 5.5 through OpenRouter, same loop and system prompt as above. That is 1.25x fewer calls, 49% fewer input tokens, half the time and 46% less cost: a smaller gap than on the settings rig, because this flow is short (a sign-in and three taps) and the tree agent never had to scroll. Raw runs and transcripts (the test credentials and the app name are replaced) are in bench/model/results/2026-11-20.crowdia.*; run it from a clone with SCENARIO=live node bench/model/run.ts.
Things this run taught us, none of which the rig showed:
- A bridge only knows what the app registered. Our first build hooked only Settings. The agent had no way to reach the sign-in screen, pressed Settings while signed out, flipped switches that silently did nothing, and gave up (the tree agent signed in without trouble). Register the way into each screen, not just the screen.
- Do not make an action wait on the network. With the switch actions returning their save promise, one
actwith three switches timed out at 30 s although the saves had happened; the model then repeated them and wrote 2 extra consent rows. Starting the save and returning (void save(...)) fixed it. Counted runs had no repeat writes. - One slow call is a lot of the spread. One bridge run took 45 s, 36 s of it in one tool call on the staging round trip; the other two took 11 s and 18 s. Three runs do not say how often that happens.
- The numbers are still one flow, one model and an emulator with a software GPU.
For the shortest-possible-path floor with no model, npm run bench (from a clone of the repo; bench/ is not in the npm package) reproduces the scripted comparison: 2 tool calls and about 540 tokens through the bridge, 13 calls and about 8,000 through the tree.
Limits
- It exposes what your components register. A component that does not call the hook is invisible to the agent; the accessibility tree is still the fallback for those.
- Registration is by hand, one hook per control. There is no codegen and no automatic walk of your tree.
- The bridge does not authenticate a transport. Start it only in builds you test (
__DEV__, or a flag), and put your own check in front of any socket you open. - Labels and row text come from the app and can contain what users typed: the tool descriptions tell the model to treat them as data. That is guidance to the model, not a guarantee.
confirmis as strong as yourallow. Withoutallow, the step fails, which is the safe default.- Tested with Node and
react-test-renderer, and run on an Android emulator inexamples/expo-app(repo only) and in one production app's branch (see above) (Expo SDK 58, React Native 0.88, new architecture, a release build). iOS and a real device have not been tried.
Testing a component with the hook
The hook is tested with react-test-renderer. Import act by name and set the act flag, or act is not a function under React 19:
import TestRenderer, { act } from "react-test-renderer";
(globalThis as any).IS_REACT_ACT_ENVIRONMENT = true;

await act(async () => { TestRenderer.create(<DeployAlerts />); });
await act(async () => { await createAgent().act({ steps: [{ ref: "Email Deploy failures", action: "setChecked", args: [true] }] }); });
The full test is test/react.test.tsx; it passes a private Registry as the hook's second argument so tests do not share state.
Credit
The bridge's shape (tool names, step format, allow, the confirm / hidden / secret marks, the benchmark task and measures) is from vercel-labs/ui, Apache-2.0. No code was copied. See NOTICE.
MIT, BeddaTech, LLC. A Bedda Labs package: small open-source pieces of the system that runs our agents.
Released 2026-11-22. MIT, BeddaTech, LLC.